
Title
Language models to characterize protein sequences: their power, challenges, and future directions
Abstract
In recent years, protein language models (PLMs) have emerged as a new technique for modeling the biological “grammar” that governs the behaviors of proteins. PLMs have enabled a diverse set of applications including structure determination, functional property prediction, and mutation impact assessment, all from single protein sequences alone. I will overview proteins and PLMs, and then discuss how my group is using PLMs in a variety of applications. I will describe our efforts to uncover in which scenarios PLMs work best, with the goal of informing their future training and application. I will also introduce a “locality aware pooling” approach for representing protein sequences that we have demonstrated works well in a wide range of biological applications. I will conclude by discussing promising avenues for future work.
Bio
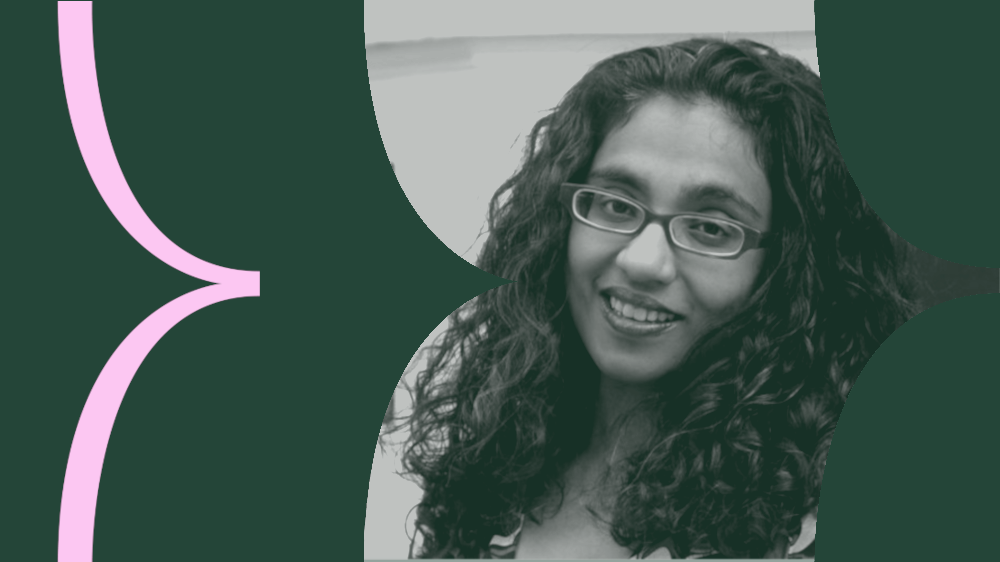
Mona Singh is the Wang Family Professor in Computer Science at Princeton University, where she is jointly appointed in the Computer Science department and the Lewis-Sigler Institute for Integrative Genomics. Mona obtained her AB and SM degrees at Harvard University, and her PhD at MIT, all three in Computer Science. She did postdoctoral work at the Whitehead Institute for Biomedical Research. She received the Presidential Early Career Award for Scientists and Engineers (PECASE), and is a Fellow of the International Society for Computational Biology and a Fellow of the Association for Computing Machinery. She is currently Editor-In-Chief of the Journal of Computational Biology.
Practical
Speaker is presenting in person.
Integreat guest talks are open for attendance.
For those unable to attend in person: https://uio.zoom.us/j/62535744013
Point of contacts:
- Organiser and moderator: Professor Arnoldo Frigessi, University of Oslo
- Integreat Administrative Leader Maria Dikova, University of Oslo